vSubtitle

New Here? Get Your First 30 Minutes FREE - Limited Time Only!

Video SEO

how-universities-can-make-video-content-accessible
Accessibility & Compliance, Higher Education, Video SEO

How Universities Can Make Video Content Accessible

Thousands of hours of lecture recordings, course content, and campus video sit across every university’s LMS, YouTube channel, and department drives — mostly untouched, mostly non-compliant. Key Takeaways Lecture recordings. Training modules. Course content. Orientation materials. Webinars. Every university has accumulated years of this material across its learning management system, YouTube channel, department drives, and individual faculty hard drives — and most of it was never built with accessibility in mind. That gap used to be a soft compliance risk. It’s now a hard, named legal standard with a real deadline attached. Under the Department of Justice’s 2024 rule for ADA Title II, public universities and colleges must bring their video, audio, and digital course content into conformance with the Web Content Accessibility Guidelines, version 2.1, Level AA — a technical standard published by the World Wide Web Consortium (W3C) and formally adopted as the legal benchmark on ADA.gov. This guide covers what that standard actually requires for video specifically, where universities most commonly fall short, and a practical rollout plan for closing the gap. The Legal Landscape in 2026 The Department of Justice published its Title II final rule in April 2024, formally naming WCAG 2.1 Level AA as the required technical standard for state and local government entities — a category that includes essentially all public universities and colleges, since population thresholds are calculated at the state level. In April 2026, just days before the original deadline, the DOJ issued an Interim Final Rule extending both compliance dates by one year. Importantly, the DOJ was explicit that the extension delays the compliance date only — it does not pause or suspend the underlying obligation to provide accessible services, and private litigation risk continues in the meantime. Institution Size Original Deadline Extended Deadline (as of April 2026) Public entities serving 50,000+ population (covers nearly all public universities) April 24, 2026 April 26, 2027 Smaller entities and special district governments April 26, 2027 April 26, 2028 This clarity is relatively new. Before the 2024 rule, accessibility expectations for higher ed video were shaped largely by DOJ resolution agreements and litigation — including a well-known case involving the University of California, Berkeley that required remediation of inaccessible online video content, and lawsuits involving Harvard and MIT that reinforced expectations around video captioning specifically. Those cases established that accessibility was required; the 2024 rule is what gave institutions a single, measurable, named standard to build toward, published in the Federal Register and detailed further on ADA.gov’s implementation guidance. Private institutions aren’t directly covered by ADA Title II, which applies specifically to state and local government entities, but private colleges and universities generally fall under ADA Title III as places of public accommodation, and courts have applied similar accessibility expectations there. Federal funding recipients — which includes most private institutions receiving federal financial aid dollars — also face parallel obligations under Section 504 of the Rehabilitation Act. What WCAG 2.1 AA Actually Requires for Video “Accessible video” is more specific than most institutions initially assume. WCAG 2.1 Level AA breaks the requirement into several distinct success criteria, and satisfying one doesn’t automatically satisfy the others: WCAG Success Criterion What It Requires 1.2.1 – Audio-only and Video-only (Prerecorded) A text alternative (transcript) for audio-only content like podcasts, and either an alternative or audio track for video-only content 1.2.2 – Captions (Prerecorded) Synchronized captions for all prerecorded video with audio — a standalone transcript does not satisfy this on its own 1.2.3 / 1.2.5 – Audio Description Narration of key visual information (slides, diagrams, demonstrations, on-screen text) not already conveyed in the spoken audio 1.2.4 – Captions (Live) Real-time captions for live synchronized media, including live-streamed lectures, webinars, and Zoom or Teams sessions 1.4.3 – Contrast Caption text and any on-screen text must meet minimum contrast ratios for readability 2.3.1 – Three Flashes or Below Threshold Video content must not contain flashing that could trigger photosensitive seizures Player accessibility (multiple criteria) The video player itself must be operable by keyboard alone, with accessible controls for play, pause, volume, and caption toggling Two details here catch most institutions off guard. First, a transcript published next to a video does not satisfy the captioning requirement — WCAG specifically requires synchronized, timed text, not just adjacent reading material. Second, audio description is treated as a genuinely separate requirement from captions, not an optional extra: if a lecture video shows a slide with text or a diagram that’s never described out loud, a blind or low-vision student has no way to access that information even with perfect captions. One survey found only about 23% of educators currently include audio description, meaning the large majority of institutional video may already fail this specific criterion regardless of how well captioning has been handled. Where Universities Most Commonly Fall Short Lecture Capture and Course Content This is typically the largest remediation surface by volume — years of recorded lectures, often produced with auto-captioning turned on and never reviewed. Auto-generated captions are a reasonable starting point, but accuracy on technical, discipline-specific vocabulary and accented speech is consistently where institutional audits find the most failures. Faculty-Uploaded and Department-Level Content Centrally managed video (official university YouTube channels, flagship course platforms) is far more likely to be captioned than video uploaded directly by individual faculty or departments to a course site, a shared drive, or a personal platform account — content that frequently falls outside any centralized accessibility review entirely. Live and Synchronous Sessions Live-streamed lectures, webinars, and virtual office hours conducted over Zoom or Teams need real-time captions under WCAG 1.2.4, a distinct requirement from prerecorded content — and one that’s easy to overlook since it requires a different technical setup than simply captioning a finished recording afterward. Everything Layered on Top of the Player The accessibility obligation doesn’t stop at the video file itself. Interactive elements layered on top — embedded quizzes, discussion panels, note-taking tools — have to be operable by keyboard and legible to a screen reader independently. A video with
open-captions-vs-closed-captions-vs-sdh
Subtitling Standards, Accessibility & Compliance, Video SEO

Open Captions vs Closed Captions vs SDH

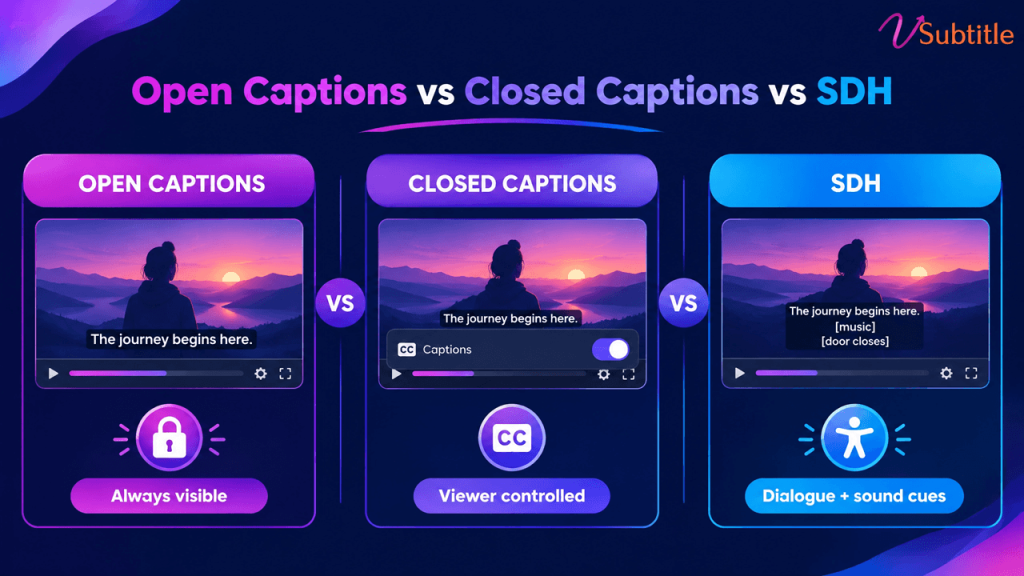
Open a streaming menu and you’ll see “English,” “English [CC],” and “English SDH” listed like three flavors of the same thing. They’re not — and mixing them up in a delivery brief is one of the more expensive mistakes in video production. “Captions,” “subtitles,” and “SDH” get used interchangeably in everyday conversation, but they describe genuinely different things — different content, different technical delivery, and in many cases, different legal requirements. The confusion isn’t just semantic. Deliver translated subtitles when a broadcaster specifically asked for closed captions, and the file gets rejected, because it’s missing the non-speech audio information a deaf viewer actually needs. Caption use overall has grown enormously in recent years — by some measures over 500% since 2021 — which means more teams than ever are producing these files without necessarily knowing which one they’re supposed to be making. This guide breaks the three terms apart cleanly: what each one actually contains, how each is technically delivered, when each is legally required, and how to decide which one a given piece of content actually needs. Two Separate Questions Hiding Inside These Labels Most of the confusion clears up once it’s clear that “open vs. closed” and “captions vs. subtitles vs. SDH” are actually answering two different questions: These two questions are independent of each other. A file can be closed (toggleable) and contain subtitle-only content, or closed and contain full caption-level detail, or — as with SDH — be delivered as a subtitle-style file that actually carries caption-level content. Keeping the two questions separate is the single fastest way to stop the terms from blurring together. Open Captions Open captions are burned permanently into the video image itself. There’s no separate track and no toggle — the text is part of the picture, indistinguishable from the rest of the frame to the video player. Whoever watches the video sees the captions; there’s no way to turn them off. This is the format used almost universally across TikTok, Reels, and YouTube Shorts content, precisely because it guarantees the text shows up regardless of device, app, or whether a viewer even knows captions exist as a feature to enable. For a format built around muted, scroll-past viewing, that guarantee is the entire point — a viewer who scrolls past with the sound off sees the text immediately, with zero extra steps. Open captions are also gaining ground beyond social video specifically: several US states and cities have passed legislation requiring movie theaters to offer a set number of open-caption screenings, reflecting a push to make accessibility the default experience in at least some showings rather than something that requires a special device. For creators producing vertical social content where open captions are standard, our Instagram Reel caption generator is built specifically around this burned-in format and the safe-zone placement it requires. Closed Captions (CC) Closed captions are stored as a separate track from the video and decoded on request — the viewer can toggle them on or off, and they’re delivered as caption data rather than baked into the video image. Content-wise, closed captions are built for viewers who can’t hear the audio at all: they include not just dialogue, but speaker identification, sound effects, and music cues — everything a hearing viewer would otherwise pick up from the audio track itself. Closed captions carry real legal weight in the US specifically. The 21st Century Communications and Video Accessibility Act (CVAA) requires that video previously aired on television include closed captions when distributed online, following broadcast technical standards like CEA-608 or CEA-708, enforced by the FCC. This is distinct from WCAG-driven web accessibility requirements, which apply more broadly to any prerecorded video with synchronized audio, regardless of broadcast history. SDH: Subtitles for the Deaf and Hard of Hearing SDH is where the content question and the delivery question intersect in a way that trips people up the most. SDH delivers caption-level content — dialogue, sound effects, speaker labels — inside a subtitle-style file format, rather than through a broadcast-style closed-caption track. It was created specifically to bridge a gap traditional subtitles couldn’t fill: subtitles assume the viewer can hear everything except the dialogue, while SDH assumes the viewer can’t hear any of it, but still gets delivered in the more flexible, easily portable subtitle file format. This is why streaming platforms overwhelmingly use SDH rather than traditional broadcast-style closed captions: subtitle files travel far more easily across different streaming apps and devices than a broadcast CC signal does, and SDH — unlike traditional closed captions — can also be translated into other languages while retaining its full caption-level content. On a service like Netflix, what’s often labeled “English [CC]” in the menu is, technically, SDH. For a deeper look at why this distinction matters for genuine accessibility — not just technical compliance — our guide to making video content deaf-friendly covers what separates a merely-present caption track from one that actually serves a deaf or hard-of-hearing viewer well. Side-by-Side Comparison Factor Open Captions Closed Captions (CC) SDH Can the viewer turn it off? No — burned into the video Yes — separate toggleable track Yes — separate toggleable track Content included Varies by use — often dialogue only Dialogue, speaker IDs, sound effects Dialogue, speaker IDs, sound effects Can it be translated? Rarely, without a new burned-in version Not typically Yes — a key advantage over traditional CC Common file formats Burned-in MP4 (no separate file) SCC, CEA-608/708 TTML, SRT, VTT (subtitle-style formats) Typical use case Social video (TikTok, Reels, Shorts), some theater screenings US broadcast and previously-aired content distributed online Streaming platforms (Netflix, Amazon Prime Video, and similar) Governed by Platform norms, some local theater legislation CVAA / FCC (for prior-broadcast content) Platform-specific delivery specs; WCAG-aligned Which One Do You Actually Need? The right choice depends on the platform, the audience, and — increasingly — the specific legal framework the content falls under, rather than a single universal answer: For a fuller walkthrough of how these accessibility

mistakes-reduce-viewer-retention-poor-captions
Subtitling Tips, Content Creation, Video SEO

Mistakes That Reduce Viewer Retention Through Poor Captions

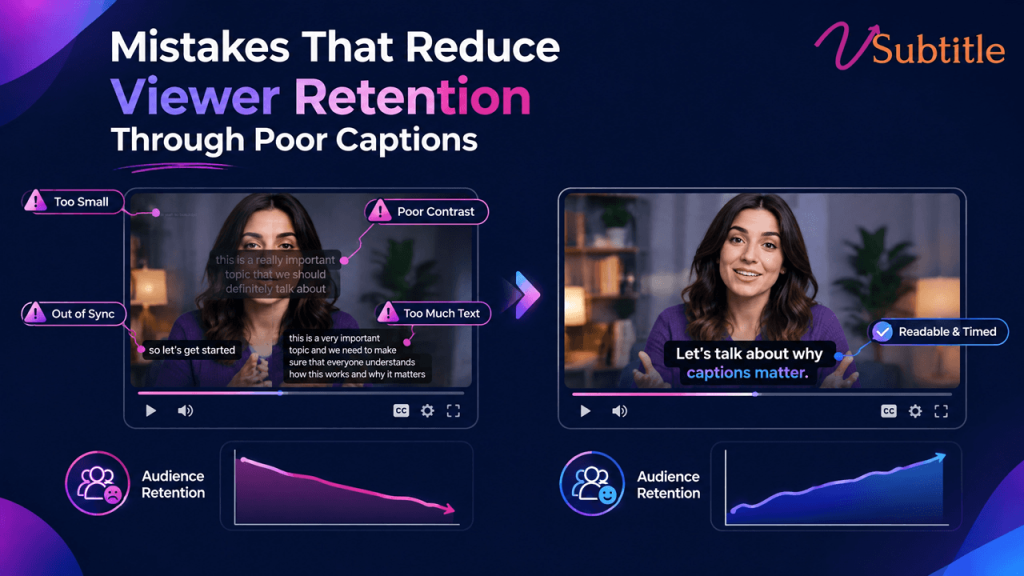
Captions are supposed to keep people watching. Done badly, they do the opposite — and most creators never realize the caption is what made someone leave. Captions have become baseline infrastructure for video in 2026, not an optional add-on — driven by sound-off viewing habits now estimated above 70% on mobile, tightened accessibility enforcement, and the reality that short-form video delivers the highest marketing ROI of any video format. The problem is that “has captions” and “has good captions” get treated as the same achievement, and they aren’t. Raw, unreviewed auto-generated captions typically carry a 5–10% word error rate, and errors in brand names, technical terms, and homophones are exactly the kind of mistake that turns a caption from a retention tool into a retention leak. This guide walks through the specific caption mistakes that quietly cost creators and brands watch time — some obvious once named, others easy to miss even in an otherwise careful production process — along with what actually fixes each one. Why Caption Quality Is a Retention Problem, Not Just a Polish Problem A caption doesn’t need to be wrong to hurt retention — it just needs to add friction between the viewer and understanding what’s happening on screen. Every extra half-second spent squinting at small text, re-reading a garbled phrase, or losing a caption behind an interface element is a small tax on attention, and attention is the one resource a viewer won’t get back once they’ve scrolled away. Multiply that friction across dozens of small moments in a single video, and a technically “captioned” piece of content can still underperform an uncaptioned one produced with more care. The Mistakes That Actually Cost Retention 1. Publishing Unedited Auto-Generated Captions Raw auto-captions carry a meaningful error rate even with clean audio, and the errors cluster exactly where they hurt most: brand names, technical terms, acronyms, and unusual proper nouns. A SaaS product’s core metric turned into nonsense, a medical term transcribed incorrectly, a founder’s own company name spelled wrong throughout an interview — these don’t just look unprofessional, they actively damage comprehension and credibility in exactly the high-trust content where accuracy matters most. The fix: treat auto-captions as a first draft, not a final deliverable, with every line reviewed at minimum for names, numbers, and specialized vocabulary before publishing. 2. Text That’s Too Small to Read Comfortably Captions sized for a desktop preview routinely fail on the actual device most viewers use. Undersized text forces a choice between straining to read and giving up — and research on this specifically finds that captions too small to read comfortably hurt retention more than captions that feel slightly oversized, meaning the safer error, if one has to be made, is erring larger rather than smaller. The fix: test captions on the smallest phone screen realistically expected in the audience, not just a desktop editor’s preview window, and size text so it’s comfortably readable without zooming. 3. Poor Timing and Sync Captions that appear too early, linger too long, or shift out of sync with shot changes break the connection between what’s said and what’s shown. Professional timing practice keeps each caption on screen for roughly one to six or seven seconds, synchronized to cuts and shot changes, with faster-paced scenes getting shorter captions so the viewer can read and still follow the visual action rather than being forced to choose one or the other. The fix: sync captions to natural speech and shot boundaries rather than a rigid, evenly spaced timing pattern, and shorten captions during fast-cut sequences specifically. 4. Reading Speed That Outruns the Viewer The widely used professional ceiling sits around 17–20 characters per second for adult content, lower for children’s programming. Captions timed faster than that ask viewers to choose between finishing the line and following the video — and most viewers, faced with that choice repeatedly, choose to stop watching rather than keep working to keep up. The fix: check reading speed directly rather than assuming a caption “looks about right” — split long lines or extend display duration rather than compressing text into a shorter window than a viewer can realistically read. 5. Low Contrast and Poor Font Choices Thin fonts, low-contrast color combinations, and styling that looks fine against one background but disappears against another are a common failure point, especially once creators start customizing caption style away from a platform’s tested default. TikTok’s own default style — white text with a black stroke — exists because it holds up reliably across a huge range of backgrounds; many customization mistakes happen exactly when creators move away from that kind of proven, high-contrast baseline in favor of something that looks better in a single preview frame but fails elsewhere in the video. The fix: keep a strong stroke or shadow on any custom caption style, and check legibility across the actual range of backgrounds the video moves through, not just one representative frame. 6. Captions Hidden Behind Platform Interface Elements A technically well-made caption that lands underneath a platform’s interaction icons, progress bar, or caption-field text is functionally invisible — a completely preventable failure that has nothing to do with the caption’s wording or timing and everything to do with where it sits in the frame. This is an increasingly common mistake as platforms expand their own UI footprint over time, meaning safe-zone guidance that was accurate a year or two ago can quietly go stale. The fix: preview finished video on an actual device before publishing, checking specifically for overlap with current platform UI — not just the safe-zone measurements used the last time captions were styled. This is a mistake with a direct fix built into a platform-specific workflow — our Instagram Reel caption generator accounts for current safe-zone placement automatically, which removes this failure mode without requiring a manual re-check on every upload. 7. Mistranslated or Poorly Adapted Subtitles for Global Audiences Direct, literal translation frequently breaks subtitle timing, because languages don’t carry the same information density as

linkedin-video-captions-why-b2b-videos-need-them
B2B Marketing, Social Media, Video SEO

LinkedIn Video Captions: Why B2B Videos Need Them

Your buyer is watching your video between meetings, on a commute, or with a laptop muted in an open office. If it isn’t captioned, your pitch never actually reaches them. LinkedIn video has moved from a nice-to-have format to one of the platform’s fastest-growing content categories, with video uploads climbing at double-digit rates for several consecutive quarters and paid video ad spend up roughly 30% year over year. For B2B marketers specifically, that growth matters more than the equivalent shift on a consumer platform, because LinkedIn’s audience skews heavily toward exactly the buyers, decision-makers, and specialists a B2B pipeline depends on — professionals in B2B companies make up the majority of the platform’s video-viewing audience. None of that growth matters if the video isn’t actually being understood. Somewhere between 75% and 85% of LinkedIn video is watched with the sound off — a habit driven by exactly the professional contexts B2B buyers are in: an open office, a meeting room between calls, a phone scrolled quietly during a commute. A B2B video without captions isn’t reaching a smaller audience on LinkedIn specifically — it’s reaching a smaller version of the exact audience the format is supposed to be built for. This article covers what the current data shows about captions and LinkedIn video performance, and the specific ways B2B marketers are using them to turn muted scrolling into real pipeline engagement. What the Data Shows About Captions on LinkedIn Finding Why It Matters for B2B 75–85% of LinkedIn video is watched with sound off The overwhelming majority of a B2B video’s audience never hears the narration unless captions are present Captioned videos retain viewers 32% longer than non-captioned videos Directly protects watch time on content built to explain a product, case study, or point of view in detail Captioned, autoplay-enabled videos see 29% more engagement LinkedIn’s feed autoplays muted by default, making captions the first and often only content a scrolling viewer sees LinkedIn video generates 1.4x more engagement than other content formats Video is already an above-average format on LinkedIn; captions protect and extend that advantage rather than undermine it Shorter videos under 15 seconds see 57% completion rates Reinforces that B2B hooks need to land fast and land as readable text, not just narration 61% of LinkedIn’s video-viewing audience works in B2B companies, with marketing, sales, and tech professionals making up 47% of all interactions This is precisely the audience segment most B2B content is trying to reach — losing them to a muted scroll has an outsized cost LinkedIn’s own Creative Labs research, based on an analysis of more than 13,000 B2B video ads and over 550,000 video frames, points the same direction: face-to-camera, vertical-friendly formats paired with captions consistently align with stronger creative performance, reflecting a broader shift in what works on the platform — a mix of LinkedIn’s traditional “professional utility” content (explainers, expert takes, proof points) with the shorter, faster-paced, caption-driven norms of feed-based social video more broadly. Why B2B Video Needs Captions More Than Most Content This connects to a broader pattern worth understanding across any embedded video content: our guide to AI subtitles and video SEO covers how the same captioning discipline that protects watch time on LinkedIn also extends a video’s discoverability wherever else it’s published or embedded. Caption Strategies That Work Specifically for LinkedIn B2B Video 1. Write the Opening Line to Work as Text Alone Since feed autoplay starts muted, the first caption a viewer sees functions as the actual hook — not a supporting element beneath a spoken hook they haven’t heard yet. Scripting the opening statement so it lands clearly as on-screen text, independent of audio, is one of the highest-leverage changes a B2B video team can make. 2. Keep Videos Short and Caption for Fast Completion With sub-15-second videos already seeing notably higher completion rates than longer content, and LinkedIn’s own guidance pointing toward the 30–90 second range for feed video, captions need to be timed for quick, confident reading rather than a slower, more deliberate pace — every extra second a caption asks a viewer to linger works against the completion window LinkedIn’s shorter formats are built around. 3. Prioritize Captioning on Testimonials and Demos Testimonials and product demos are consistently cited as the highest-converting B2B video formats, since they offer the fastest route to credibility with a prospective buyer. These are also the formats where a caption error is most costly — a misheard statistic or client name on a testimonial undercuts the exact trust the format is meant to build, making an accuracy review non-negotiable here even when time is tight elsewhere. 4. Caption Personal-Profile Video, Not Just Company Page Content Posts from individual profiles on LinkedIn draw substantially more engagement than identical content posted from a company page — a gap large enough that B2B organizations increasingly route video through founders, executives, and subject-matter experts rather than the brand account alone. Captioning discipline needs to extend to this content too; a well-captioned company-page video and an uncaptioned executive video from the same campaign are giving up real performance on the higher-engagement channel. 5. Upload Natively and Caption for LinkedIn’s Own Environment LinkedIn consistently favors natively uploaded video over links to YouTube or other platforms, and native upload means captions need to be prepared for LinkedIn’s own player and safe zones specifically, rather than reused directly from a YouTube version without checking placement and formatting. How Captions Feed Back Into LinkedIn’s Own Distribution The retention and completion gains captions produce aren’t just a viewer-experience improvement — they directly influence how much distribution a video earns. LinkedIn’s algorithm, like most feed-based platforms in 2026, weights watch time and completion heavily in deciding how far a post travels beyond a creator’s immediate network. A captioned video that holds attention for 32% longer than its uncaptioned equivalent isn’t just performing better with the audience it reaches — it’s earning the engagement signal that leads to a wider one. This same dynamic — captions improving both

how-brands-increase-video-engagement-captions
Video SEO, Marketing & Branding, Social Media

How Brands Increase Video Engagement Using Captions

The best-performing brand video in 2026 isn’t necessarily the best-produced. It’s the video that still works with the sound off. Video marketing has reached near-universal adoption — the large majority of businesses now use it as a core part of their strategy — which means the competitive question for brands has quietly shifted. It’s no longer whether to use video, but how to make video actually perform once everyone is already using it. One lever shows up across nearly every 2026 study on the subject as one of the highest-leverage, lowest-cost ways to move that needle: captions. This isn’t an accessibility footnote anymore. Brands running captions as a default, not an afterthought, report measurably higher completion rates, stronger recall, and better brand affinity scores than the same content without them. This article breaks down exactly why captions move these numbers, what the current data shows, and the specific strategies brands are using to turn a basic accessibility feature into a genuine engagement lever. What the 2026 Data Actually Shows The starting fact behind all of this is simple: most branded video is watched without sound. On LinkedIn specifically, roughly 80% of video is watched muted, which is why the large majority of video published there is now deliberately designed for silent viewing with on-screen text or captions built in from the start rather than added afterward. That pattern holds broadly across platforms, not just LinkedIn. Finding Source Context 85% of social media video is watched without sound Consistent across multiple 2026 video marketing datasets Captioned videos see roughly 40% higher completion rates on average Short-form video performance research, 2026 80% of LinkedIn video is watched with no sound; 70% of video is designed for silent viewing as a result LinkedIn-specific video marketing data, 2026 50% of silent-viewing audiences rely on captions to understand video content at all General video marketing statistics, 2026 TikTok ad videos with captions see a 95% boost in brand affinity, a 58% increase in recall, and a 25% jump in perceived uniqueness TikTok ad performance data, 2026 Completion rate, not view count, is the metric platforms increasingly weight in distribution Cross-platform algorithm behavior noted across multiple 2026 sources The pattern across every one of these numbers is the same: captions aren’t just making video accessible to a wider audience, they’re materially changing how much of that audience actually finishes watching, remembers what they saw, and forms a favorable impression of the brand behind it. For a discipline as metric-driven as modern marketing, that’s a rare case of an accessibility improvement and a performance improvement being the exact same piece of work. Why Captions Move Brand Engagement Metrics Specifically They Remove the Single Biggest Barrier to Silent Viewing With the substantial majority of social and feed-based video watched muted, a caption-free video is only reaching a minority of its actual audience with its full message. Everyone else gets visuals and, at best, an incomplete guess at the audio’s content — a gap captions close directly and immediately. They Reinforce the Message Through a Second Channel For the portion of the audience watching with sound on, captions don’t just repeat the audio — they reinforce it through a second, simultaneous channel. This dual-channel reinforcement is a well-documented driver of the recall lift brands see from captioned content: information delivered through both audio and matching text is retained better than audio alone, which directly explains why captioned ads outperform on brand recall specifically, not just completion. They Feed Platform Algorithms Directly Most major platforms now weight completion rate and watch time heavily in how widely a video gets distributed, and several read on-screen text through OCR to help categorize and match content to relevant searches or recommendations. A captioned video isn’t just more watchable — it’s giving the platform more signal to work with when deciding who else to show it to. They Signal Production Quality and Brand Care A large share of consumers say video quality directly affects how much they trust a brand. Clean, well-timed, accurately worded captions are part of that quality signal now, in the same way a shaky, poorly lit video used to read as low-effort — an uncaptioned video in 2026 increasingly reads the same way, regardless of how polished the footage itself is. This connects directly to the SEO side of the same coin: our guide to AI subtitles and video SEO covers how the same caption and transcript work that lifts engagement also improves discoverability, meaning brands investing in captions are typically getting two separate performance gains from one piece of production work. H2 Caption Strategies Brands Use to Drive Engagement 1. Design for Sound-Off From the Script Stage, Not as a Caption Afterthought Leading brand video teams now treat captions as part of the creative brief, not a post-production checkbox — scripting the opening line with the assumption it needs to land as text on screen, not just as narration. A hook that only works with audio loses its entire effect on the majority of viewers who never unmute. 2. Use Animated, Word-Synced Captions for Short-Form and Social Word-by-word or short-phrase animated captions, timed to match speech, have become a standard style for high-performing short-form brand content specifically because the motion keeps attention anchored the way a static caption block doesn’t. Bold, high-contrast fonts optimized for mobile screens consistently outperform thinner, more decorative styles once a video is actually watched on a phone rather than previewed on a desktop editor. 3. Treat Caption Styling as Part of Brand Identity Consistent caption fonts, colors, and animation style across a brand’s video output function similarly to a consistent color palette or logo placement — viewers start to recognize the brand’s content by its caption style alone, especially on platforms where content from many creators and brands blends together in a single feed. This is a detail smaller teams often skip, treating captions as purely functional rather than as a piece of visual identity worth designing deliberately. 4. Localize Captions for Global

geo-generative-engine-optimization-videos-subtitles
AI Search & GEO, Subtitling Tips, Video SEO

GEO (Generative Engine Optimization) for Videos: Why Subtitles Matter

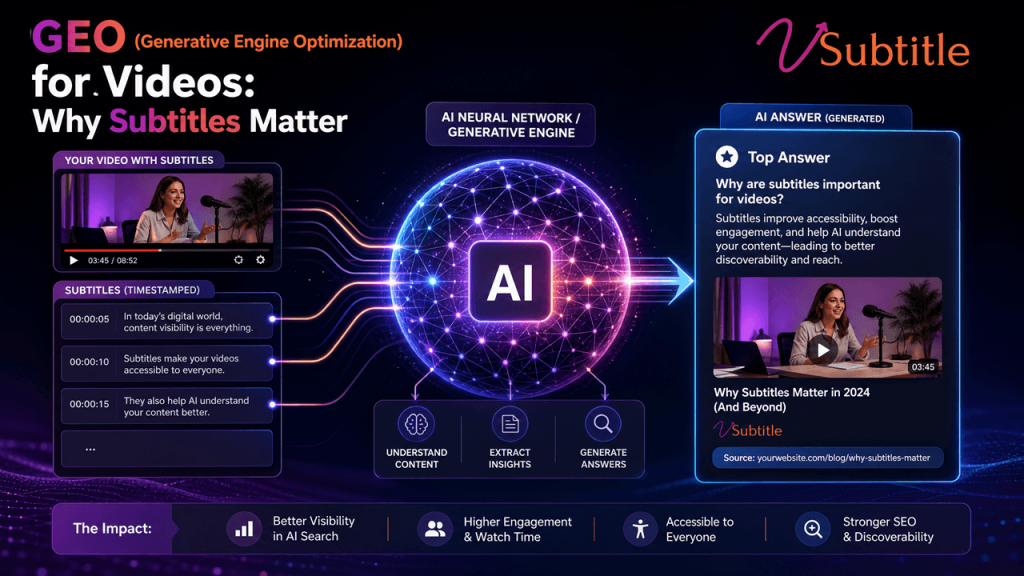
AI engines don’t rank your video. They read it, judge it, and decide whether to quote it — and subtitles are the only part of a video built for that job. Generative Engine Optimization, or GEO, is the practice of making content discoverable, trustworthy, and quotable to AI systems like ChatGPT, Perplexity, Gemini, and Google’s AI Overviews — a distinct discipline from traditional SEO, though built on many of the same foundations. The term was coined by Princeton researchers in 2023, and by 2026 it has become a core part of how any content-driven brand thinks about visibility, because a growing share of searches now resolve into a synthesized AI answer rather than a list of links to click. Video sits in an unusual position inside this shift. It’s simultaneously one of the most trusted content types generative engines cite — YouTube transcripts show up constantly in AI-generated answers — and one of the most commonly invisible, because the systems doing the citing can’t watch a video the way a person can. They can only read whatever text is attached to it. That gap between video’s citation potential and its default invisibility is exactly where subtitles and transcripts do their work, and it’s the focus of this guide. What GEO Actually Means for Content Traditional SEO optimizes for ranking position in a list of search results. GEO optimizes for something different: being the source a generative engine actually pulls from, quotes, or names when it synthesizes an answer. The two disciplines share fundamentals — crawlability, structure, authority — but GEO adds requirements SEO never needed to worry about, because a ranking position and a citation are not the same prize. A few principles specific to GEO matter directly for video: Why Video Is a GEO Blind Spot Without Subtitles Every GEO principle above assumes there’s text to evaluate. That assumption breaks down for video the moment there’s no caption track or transcript attached to it. A generative engine encountering an uncaptioned video has almost nothing to work with — a title, maybe a thumbnail, and a short description if one exists. It cannot watch the footage, and it cannot listen to the audio the way a person does. Whatever isn’t captured in text simply doesn’t exist to the system trying to decide whether to cite it. This is the same underlying dynamic covered in depth in our guide to AI subtitles and video SEO — the principle holds just as strongly, arguably more strongly, once the audience shifts from search engine crawlers to generative engines synthesizing an actual answer rather than just indexing a page. The practical result: two videos covering the exact same topic, with the exact same production quality, can have completely different GEO outcomes based purely on whether one of them has an accurate, structured transcript attached. The captioned video is eligible to be read, understood, and quoted. The uncaptioned one is functionally mute to the systems that increasingly decide what gets surfaced. How Generative Engines Actually Discover and Use Video Content YouTube specifically occupies a privileged position in GEO research: transcripts hosted there are crawled and cited frequently enough that a handful of well-titled, well-described videos with clean transcripts can outperform a blog post for the same query. That’s a notable claim — video, historically treated as SEO’s afterthought behind written content, is now one of the more reliably cited formats, provided the transcript backing it is actually there and actually accurate. This connects directly to something worth understanding about the platform itself: how AI subtitles compare to YouTube’s own auto-captions, since the accuracy and structure of that transcript — not just its existence — is what determines whether an engine trusts and reuses it. For video embedded on a company’s own site rather than YouTube, the mechanics shift slightly but the principle doesn’t: the page needs a crawlable transcript, ideally paired with VideoObject structured data, so a generative engine’s crawler has explicit, machine-readable text to work from rather than having to infer content from a title and thumbnail alone. What Makes a Video Transcript GEO-Friendly Publishing any transcript at all is a meaningful first step, but GEO rewards specific structural choices within that transcript far more than a raw, undifferentiated wall of text: Lead With a Direct Answer Generative engines favor content that answers a clear question within the first sentence or two of a section, ideally in the 40–60 word range that tends to get pulled directly into AI-generated answer boxes. A transcript or accompanying summary that opens with the actual point, rather than warming up to it, is far more extractable. Break Content Into Labeled Sections A transcript structured to mirror a video’s chapters — with descriptive subheadings — gives a generative engine a map of what’s covered where, rather than forcing it to parse an undifferentiated block of spoken text to find the relevant part. Use Lists and Tables Where They Fit Steps, comparisons, and data points formatted as lists or tables are consistently easier for generative engines to extract cleanly than the same information buried in prose — a structural preference GEO shares directly with how featured snippets have always worked. Increase Factual Density A transcript that includes specific figures, named findings, or sourced claims gives a generative engine something concrete to quote. Vague claims about being “the best” or “industry-leading” provide nothing extractable — a generative engine has no way to verify or cite an unsupported superlative. This same structural logic — short, scannable, answer-first sections — is also why on-page subtitles and transcripts have been shown to increase time on page: the format that makes content easiest for a generative engine to extract is very often the same format that keeps a human reader engaged. A GEO Checklist for Video Content Multilingual Transcripts Extend GEO Reach GEO isn’t limited to a single language market, and neither is the query volume flowing through ChatGPT, Perplexity, and AI Overviews worldwide. A video with only an English transcript is only eligible

ai-captions-for-product-demo-videos
Product Marketing, SaaS Growth, Video SEO

AI Captions for Product Demo Videos: Why They’re No Longer Optional

Most people evaluating your product will watch the demo with the sound off. If it isn’t captioned, they’re not watching a demo — they’re watching a silent screen recording. A product demo video carries more weight in a buying decision than almost any other piece of content a company produces. Reports indicate a large majority of buyers say a demo video played a real role in convincing them to purchase, and websites featuring one see meaningfully higher conversion rates than those without. That’s exactly why it’s worth taking seriously a detail that gets treated as an afterthought on far too many demo videos: whether a viewer can actually follow it with the sound off. The vast majority of mobile video is watched muted, and that habit carries directly into how prospects evaluate software — scrolling a homepage on a train, watching a shared demo link in an open-plan office, previewing a sales rep’s screen recording in a browser tab with the volume down. A demo video without captions isn’t just less accessible in the abstract; for most of its actual audience, it’s functionally unwatchable. This guide covers why captions matter specifically for product demo videos, what good captioning looks like for this format, and a practical workflow — using vSubtitle — for getting it right without adding hours to an already tight production timeline. The Case for Captions on Every Demo Video Product demo videos already carry outsized weight in the buyer journey. Industry surveys put the share of buyers who say a demo video influenced their purchase decision above 85%, and sites featuring demo video content report conversion rates dramatically higher than sites without one. Video-driven B2B SaaS campaigns are commonly reported to convert 40% higher than static content, and testimonial and demo formats consistently rank among the highest-converting video types B2B marketers produce. Underneath those numbers sits a simpler, more mechanical fact: the overwhelming majority of that viewing happens without sound. Independent research on mobile viewing behavior puts silent viewing above 90% on mobile and in the low 80s across devices overall, and captioned videos have been shown to hold viewers significantly longer than uncaptioned ones — one widely cited study found captioned videos were roughly 80% more likely to be watched all the way through. For a format specifically built to explain a product in enough detail to move someone toward a purchase, losing the majority of the audience to a muted screen isn’t a minor accessibility gap. It’s a direct hit to the metric the video exists to move. Stat Why It Matters for Demo Videos 85%+ of buyers say a demo video influenced their purchase The format itself is doing real persuasion work — undermining it with no captions has an outsized cost Up to 86% higher conversion on pages with demo video Captions are a low-cost way to protect that lift rather than lose most of it to muted viewers 90%+ of mobile viewers, 80%+ overall watch muted Most of a demo’s real-world audience never hears the narration unless captions are present Captioned videos ~80% more likely to be watched fully Completion matters more for demos than most formats, since the value proposition often lands in the final third Nearly half of viewers drop off before the one-minute mark A confusing or silent opening is the single biggest risk point captions directly help solve Why Product Demos Need Captions More Than Most Video Content Captions help every video format, but the case is especially strong for demos, for reasons specific to what this content is trying to do: What Good Captioning Looks Like on a Demo Video Match the Pace of the Narration, Not Just the Words Demo narration tends to move faster and more conversationally than scripted marketing video, with filler words, mid-sentence corrections, and rapid feature callouts. Captions need light cleanup — trimming filler without changing meaning — rather than a robotic word-for-word transcript that’s technically accurate but harder to read at speed. Keep Captions Clear of the UI Being Demonstrated This is the detail most generic caption placement gets wrong for screen recordings specifically: the default bottom-third position frequently sits directly over navigation bars, buttons, or the exact UI element the narrator is describing. Captions on a demo need to be positioned — and sometimes repositioned scene by scene — so they never obscure the thing the viewer is being shown. Reflect Product Terminology Exactly Feature names, menu labels, and product-specific terms need to match the actual UI precisely, not a close paraphrase. A caption that reads “click Reports” when the button says “Analytics” creates confusion at exactly the moment a prospective buyer is trying to evaluate whether the product does what they need — accuracy here isn’t a nicety, it’s core to the demo working at all. Cap Reading Speed Realistically for Technical Content Standard subtitle reading-speed guidance (roughly 15–17 characters per second for comfortable reading) still applies, but demo narration often needs slightly more room, since technical terms and product names take longer to parse than everyday words of the same length. Where possible, favor slightly longer on-screen duration for lines containing feature names or numbers over rigidly matching a general-purpose CPS target. Provide a Full Transcript, Not Just Burned-In Captions A demo video embedded on a product or pricing page benefits from the same SEO logic as any other video: a crawlable, on-page transcript gives search engines and AI answer engines the complete content of the demo to index — useful both for organic discovery and for surfacing accurate answers when a prospect asks an AI assistant what a product does or how a specific feature works. Captioning Needs Differ Across Demo Video Types “Product demo video” covers several distinct formats, and captioning priorities shift slightly across them: Homepage / Landing Page Demos These are typically short, high-traffic, and viewed by cold prospects with no context — muted-by-default browsing behavior is at its highest here, making captions close to mandatory rather than optional. Keep captions tight and

ai-captions-vs-video-descriptions-search-visibility
Video SEO, AI Search & GEO, Content Accessibility

AI Captions vs Video Descriptions: Which Improves Search Visibility More?

Both show up in the SEO checklist. They don’t do the same job — and search engines don’t treat them the same way. Ask ten video creators what actually moves the needle for search visibility, and most will mention two things: writing a solid description and turning on captions. Both are standard advice. Both appear near the top of every video SEO checklist. And both get treated, more often than not, as roughly interchangeable line items — two boxes to tick before hitting publish. They aren’t interchangeable, and the difference matters more in 2026 than it used to. A video description is a few hundred words you write about your video. An AI-generated caption file is a complete, word-for-word transcript of everything actually said in it — often ten times the length, and built from the video’s real content rather than a summary of it. When search engines and AI answer engines decide what a video is about and whether to surface it, these two text sources carry very different weight. This article compares them directly: what each one does, what the data says about their impact, and how to use both together instead of picking one over the other. What Each One Actually Is Video Descriptions A video description is manually written summary text that sits below the video on YouTube or alongside the embed on a website. It typically includes a short overview of the video, relevant keywords, links, timestamps or chapter markers, and calls to action. Best-practice guidance generally recommends at least 250 words, with important keywords placed in the first 25 words, since that opening segment is what displays before a viewer clicks “show more.” Descriptions are written for two audiences at once: the human scanning before they click play, and the search engine trying to categorize the video before it’s indexed. That dual purpose is also their limitation — a description can only say what the creator chooses to write, in the length the creator is willing to write it. AI Captions and Transcripts An AI caption file is generated directly from the audio of the video itself, using automatic speech recognition to convert every spoken word into timestamped text. The output is a caption track (SRT or VTT) that can be displayed on screen, and — critically for search — the same underlying text can be published as a full transcript on the page. Unlike a description, a transcript isn’t a summary written after the fact; it’s the complete, unfiltered content of the video, often running several thousand words for a video that’s just a few minutes long. That length and completeness is exactly what separates the two as SEO assets. A description tells a search engine what you say your video is about. A transcript shows it. Head-to-Head: What Each Format Contributes Factor Video Description AI Captions / Transcript Typical length 150–300 words, creator-written 500–3,000+ words, generated from actual spoken content Source of content Creator’s summary and framing Verbatim record of what’s actually said Keyword coverage Limited to what the creator thinks to include Naturally covers every term, phrase, and variation actually spoken Effect on accessibility None directly Required for deaf/hard-of-hearing viewers and legal compliance in many regions Effect on watch time / engagement Indirect, via clearer expectations before clicking Captions increase view completion and comprehension, especially for muted viewing Usefulness to AI answer engines Provides context and framing, but limited depth Primary source AI systems read to understand and cite spoken content Effort required A few minutes of writing per video Automated generation, plus review time for accuracy Risk if skipped Video is harder to categorize and may underperform in click-through Video becomes largely unreadable to search crawlers and AI systems Why Transcripts Carry More Search Weight Search engines cannot watch a video and understand what’s said inside it — they can only read text. A description gives them a small, curated sample of text written after the video exists. A transcript gives them the entire spoken content of the video, in the creator’s actual words, at whatever length the content naturally runs. For a search engine trying to match a video to a specific, long-tail query, that difference in raw text volume and specificity is significant: a five-minute video might yield a 250-word description but a 700-900 word transcript, and every one of those extra words is a potential match point for a search query the description never anticipated. This gap is why transcripts are frequently described as doing “double duty.” Closed captions serve the accessibility and engagement side — they widen the audience and keep muted viewers watching. But the transcript version of that same text is what hands search engines and AI systems the full content of the video, letting it be understood and indexed for far more than its title and description alone could cover. The gap widens further with AI answer engines. When ChatGPT, Perplexity, or Google’s AI Overviews evaluate a video for citation, they’re generally working from whatever transcript or caption data is attached to it. A well-written description helps them understand framing and intent; a transcript is what lets them quote a specific claim, cite a specific statistic, or answer a question your video actually addresses in detail. Research tracking YouTube visibility inside AI Overviews found that brand mentions in video titles and transcripts were the strongest single correlating signal measured — a result descriptions alone, however well written, can’t replicate at that scale. Where Descriptions Still Do Real Work None of this makes descriptions optional. They do things a transcript can’t: In short, descriptions are a precision tool for framing and clicks. Transcripts are a volume tool for comprehension and depth. Neither substitutes for the other. The Real Answer: They Compound, They Don’t Compete Treating this as a choice between captions and descriptions misreads how search engines actually evaluate a video page. Guidance across current video SEO research points the same direction: titles, descriptions, and captions each tell search engines and AI systems

video-captions-rank-chatgpt-google-ai-overviews
AI Search & GEO, Content Accessibility, Video SEO

How Video Captions Help You Rank in ChatGPT & Google AI Overviews

AI search engines don’t watch your video. They read it — and captions are the text they’re reading. Search has quietly split in two. There’s still the classic ten blue links, but increasingly, the first thing a searcher sees is a generated answer — an AI Overview at the top of Google, a synthesized response inside ChatGPT, a cited summary in Perplexity. Industry estimates now put the majority of search queries running through some kind of AI-enhanced interface, and that answer layer works on different rules than the ranking system video creators spent the last decade learning. Here’s the part that surprises most video teams: large language models don’t watch video. They can’t sit through eight minutes of footage and extract meaning the way a human viewer does. What they can do is read — and the single biggest thing standing between your video and an AI citation is whether there’s clean, accurate text attached to it. That text is your captions and transcript. This article covers exactly why that text matters, what the current data shows about it, and the specific steps that turn a captioned video into a source AI systems actually cite. Why AI Search Changed the Rules for Video For years, video SEO meant optimizing for a ranking position — get into the top of the video carousel, win the featured snippet, land on page one. AI Overviews and chat-based answer engines introduced a different prize: the citation. Instead of a list of links, the searcher gets a synthesized answer with a handful of sources named or linked underneath it. Being ranked well still matters — research analyzing hundreds of thousands of keywords found that the vast majority of AI Overviews cite at least one source from within the top twenty organic results — but ranking alone no longer guarantees a citation, and a citation is now worth more than a ranking position that nobody reads down to. Video sits in an unusually strong position inside this new layer. Google actively surfaces video directly inside AI Overviews and AI Mode, and answer engines like ChatGPT, Gemini, and Perplexity increasingly reference YouTube videos by reading their transcripts to understand what’s covered. One large-scale study of thousands of brands found that mentions in YouTube video titles and transcripts were the single strongest correlating signal with AI Overview visibility of every signal measured — stronger than backlinks, stronger than domain authority. That’s a striking result, and it points to one conclusion: the text layer wrapped around your video is doing more ranking work than the video itself. LLMs Don’t Watch Video — They Read It It’s worth being precise about what’s actually happening under the hood. When ChatGPT, Perplexity, or Google’s AI systems encounter a page with an embedded video, they aren’t decoding the pixels or listening to the audio track in any meaningful way. They’re processing whatever text is attached to that video: the title, the description, the surrounding page copy, structured data — and, critically, the transcript or caption file, if one exists and is accessible as machine-readable text rather than baked into the video frame as burned-in graphics. That means every word your presenter says on camera is invisible to an AI system unless it’s been converted into text the system can crawl. A brilliant, information-dense video with no caption file is functionally mute to an LLM — it has a title and a thumbnail and nothing else to go on. A mediocre video with a clean, accurate, well-structured transcript hands the model exactly what it needs to understand, quote, and cite the content. Between those two, the second video wins the citation every time, regardless of production value. The practical translation: captions and transcripts aren’t just an accessibility feature anymore. They are the primary channel through which AI search systems understand what your video actually says. How Google’s AI Overviews Read Your Video Google’s video indexing system works by crawling your video sitemap, reading any structured data on the page, and analyzing the transcript. A 2025 update to Google’s core systems — reported to unify several of its language-understanding models — extended this to compare what a video’s metadata claims against what’s actually spoken in it. If a title promises one topic and the spoken content never addresses it, that mismatch is now detectable and can work against the page. In other words, your spoken words and your written metadata increasingly need to agree with each other, and the caption file is what lets Google check. Three technical elements determine whether Google can use that transcript for an AI Overview citation: Pages that combine all three — a properly captioned video, a visible transcript, and valid schema — are the ones showing up as supporting citations inside AI Overviews. Each piece alone helps a little; together, they compound. How ChatGPT and Other Answer Engines Source Video Content ChatGPT doesn’t have a native way to “watch” a video link and extract its content reliably — when it references a YouTube video, it’s typically working from caption or transcript data that’s already attached to that video, either pulled directly or via a browsing tool. If a video has no captions available, tools built on top of ChatGPT generally can’t summarize or cite it at all; several video-to-text tools built specifically for this workflow exist for exactly that reason — because ChatGPT’s reliability drops sharply the moment there’s no existing transcript to work from. This is a meaningfully different failure mode than traditional SEO. A page with thin content might still rank poorly but exist in the index. A video with no captions is often simply invisible to an AI system attempting to answer a question your video actually answers well — not because the content is wrong, but because there was no text for the model to find. What the Data Shows Finding What It Means for Captions Brand mentions in YouTube titles/transcripts are the strongest single correlating signal with AI Overview visibility (Ahrefs, 75,000-brand study)

Scroll to Top